RL on rewards from a research world model, recalibrated with targeted real runs
Scroll sideways to see the whole diagram.
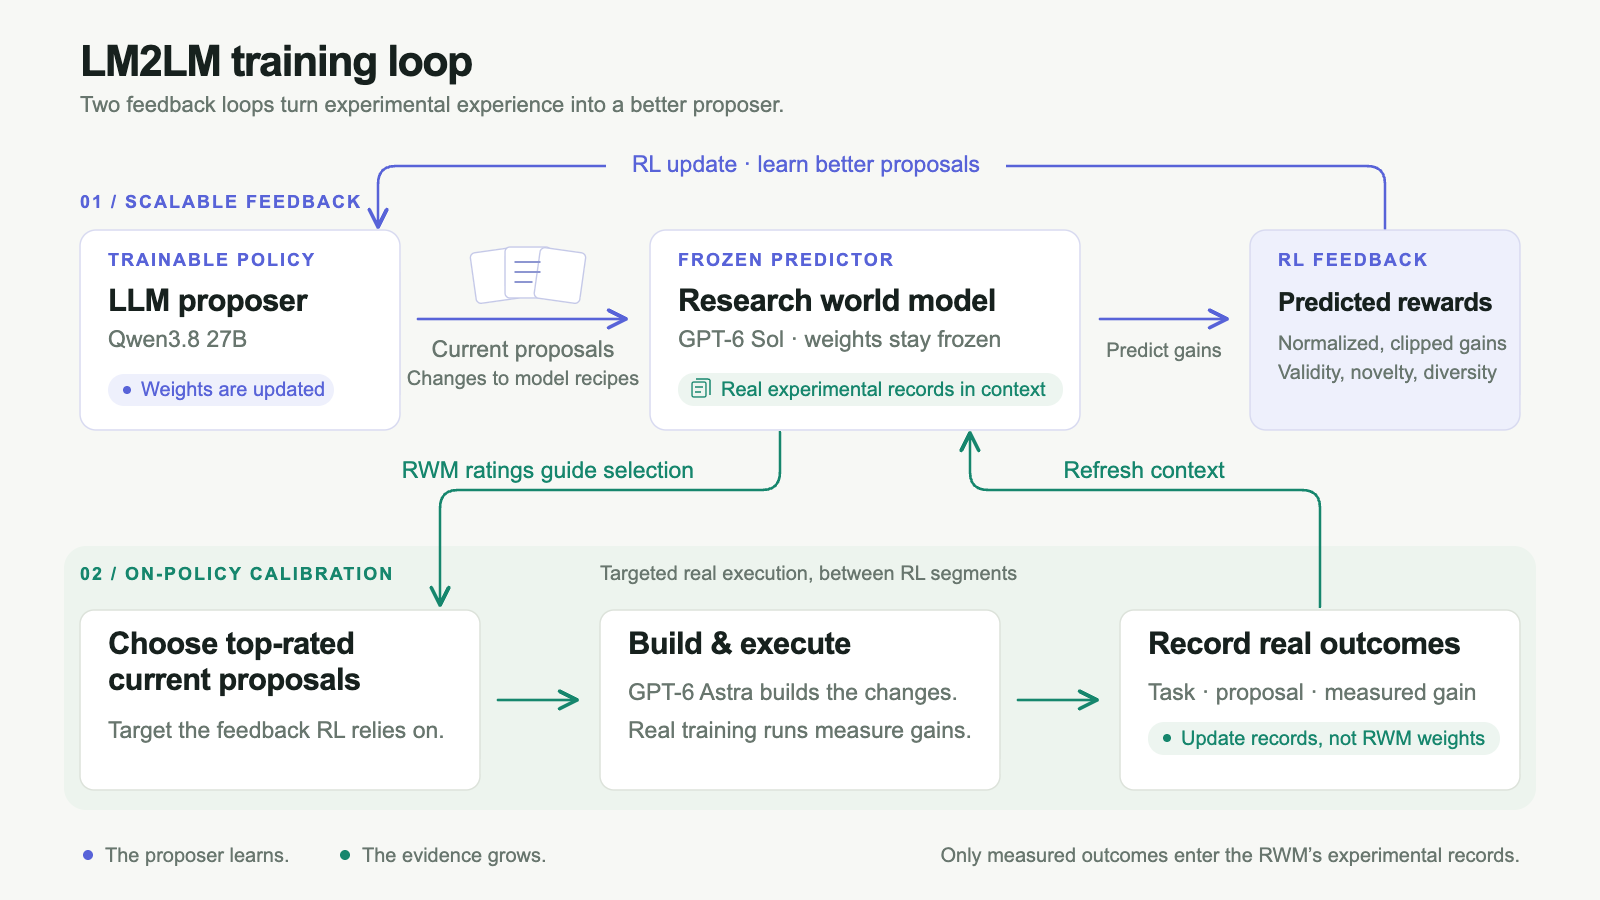

- Ground the reward. A frozen GPT-6 Sol, the RWM, reads 100 real experimental records in context and predicts each proposal’s gain over the task’s reference recipe.
- Train the proposer. Qwen3.8 27B is trained with DAPO for 96 steps on rewards built from the predicted gains.
- Calibrate on-policy. After steps 16, 40, and 64, the proposals the RWM rates highest are built by GPT-6 Astra and run for real (31, 38, and 31 runs). Their measured outcomes join the RWM’s records, so the rewards keep up with what the proposer now generates.